code · · 7 min read
I did not expect to write a hype post. I have thirty years of scar tissue from vendors telling me the new thing is the thing, and Anthropic’s launch copy for Opus 5.5 reads exactly the way launch copy always reads: it “finds the root cause before changing anything, checks its work as it goes, and explains its changes in plain language.” Fine. They all say that.
Then I spent a week with it on Scribe, my own publishing and kanban system, and most of that copy turned out to be true. What convinced me, though, was not the bits that worked. It was the two occasions it was wrong, I said so, and it went and did the reading.
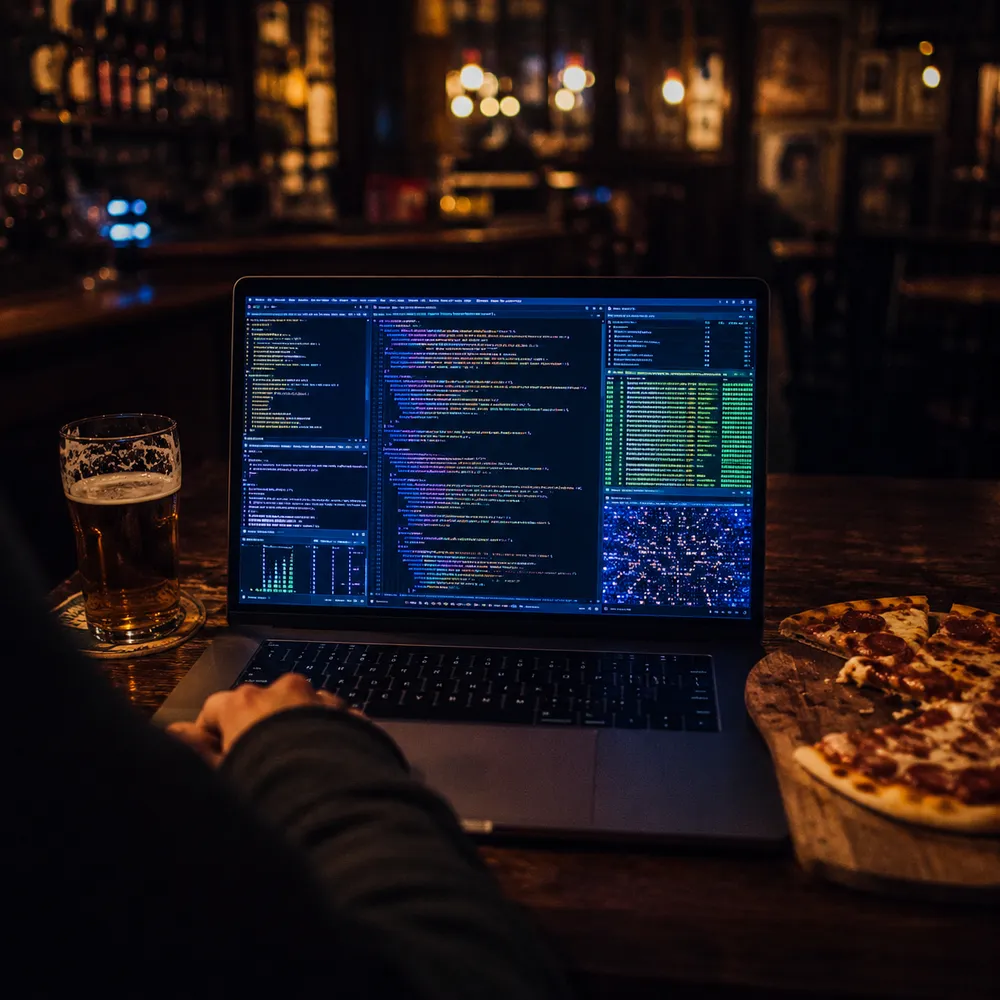
In one sitting it cleared a six-ticket bug sprint. Not six trivial tickets padded out to look like a sprint; the actual backlog I had been avoiding. Partway through I changed direction on two sites at once, which is the kind of thing that normally sends an agent into a spiral of half-applied edits. It absorbed it. Somewhere in the middle it noticed that my site’s og:image had been 404ing, which I had not noticed, and which no amount of me staring at the page would have surfaced. And then it took colindomoney.com live, with me on pub wifi, nursing a pint and a laptop that was not plugged in.
The unglamorous part of why this felt different is money and speed. Input and output are $4 and $20 per million tokens, cache reads are 60% cheaper than Opus 5, and output arrives more than 30% faster. Simon Willison points out that in long agentic sessions 90%+ of input tokens are hitting the cache anyway, so that cache cut is the number that matters. A sprint plus a direction change plus a go-live felt like an afternoon rather than a bill I would wince at.
Two things, and I want to be precise about both, because they are the point of the post.
It trusted the board over me. I told it a card was dead. Not ambiguous, not “maybe park that one”; dead, drop it. It looked at the kanban board, saw the card still sitting in a live column, and carried on treating it as work to do. The board was, in its reading, the authority. I was a comment in the margin.
It reached for a timeout. A process hung. Its first move was to put a time limit on it. That would have made the hang go away in the sense that the process would exit, and any test that only checks for exit would have gone green. I told it to find out why it was hanging. It did, quickly and well, and the fix was small. But the plaster was its first instinct.
Neither of these surprised me once I read the system card, which is the most honest document in the launch and the one almost nobody will open. Alongside the good news (less misaligned behaviour than any recent Claude model, fewer overeager or destructive actions), it lists regressions plainly: “more likely to follow malicious instructions planted in text a user pastes into their own prompt, more often accepting unverifiable claims of authorization.” My board is not malicious. But a board state is, structurally, an unverifiable claim of authorization. The card says it is live, therefore it is live. Anthropic told us it would lean on the wrong source, and in my kitchen, it did.
Here is the thing I keep coming back to. In both cases I pushed back with one sentence, and in both cases it stopped, read what it should have read the first time, and corrected course without sulking or arguing the toss. That is a colleague. A junior one, occasionally, but a colleague.
The alternative is an oracle: a model you cannot usefully disagree with, either because it does not listen or because it is so confident you stop trying. I have three decades of evidence that oracles are how security incidents start. Somebody trusts the output of a thing because the thing is usually right, and “usually” does the rest. I wrote about not wanting to hand my agent SSH in I Didn’t Want to Give My AI Agent SSH, and the reasoning there has not changed. What has changed is that the model on the other end of the leash now behaves like something you can supervise rather than something you can only switch off.
Anthropic’s own playbook for the model says, of subagents, “check its evidence before you accept it.” That cuts both ways. I check its evidence; it should check mine, and this week it needed telling to do so twice. “Finds the root cause before changing anything” is a tendency, not a guarantee.
The hype around Opus 5.5 is earned, but not for the reasons in the launch copy. The 680,000-line migration and the 39-of-40 load-time result are nice numbers that happened to somebody else. What happened to me was that a model cleared a week of work in a pub, got two things wrong, and when I said “learn to read,” it read.
That is the bar. Not never wrong. Correctable, and quick about it.